01.Project Overview
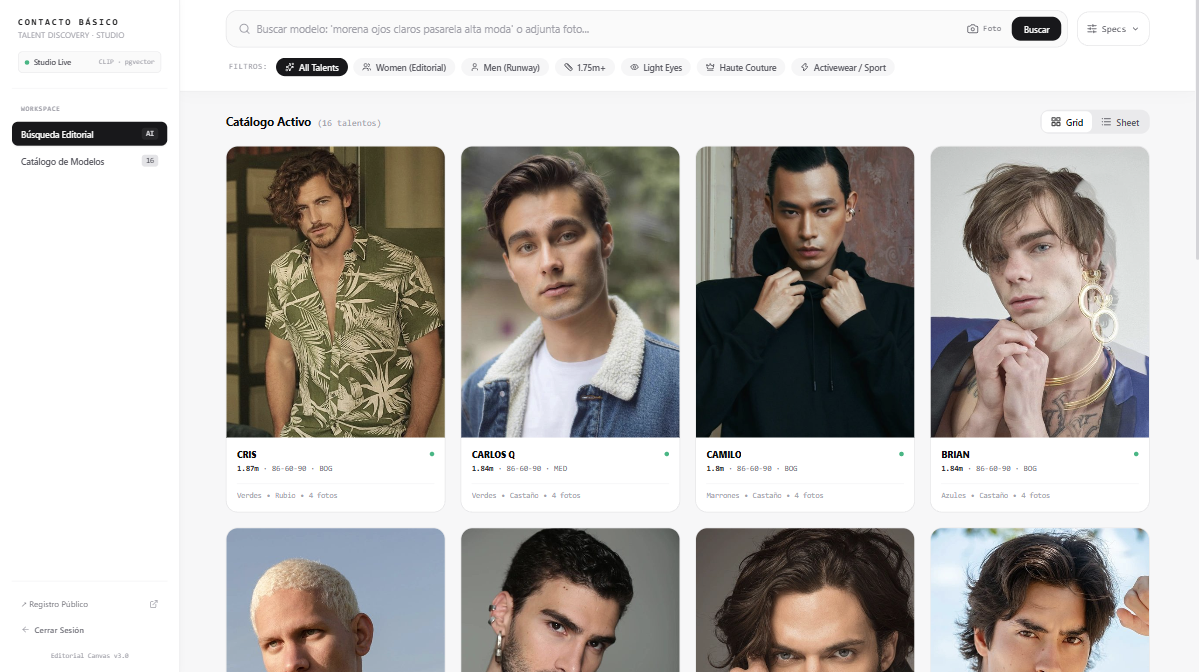
Enterprise multimodal casting platform. Discovers talent through natural language descriptions or reference photo uploads using CLIP ViT-B/32 (512d), automated biometric attribute extraction via GPT-4o-mini Vision, and two-stage retrieval with pgvector cosine similarity and SQL trait filtering.
Vector similarity search inside PostgreSQL 16 combining cosine distance with relational SQL WHERE clauses.
Extracts structured biometric attributes (hair, eyes, skin tone, measurements) automatically from comp-card photos.
Asynchronous Python API executing parallel CLIP encoding, candidate pool expansion, and composite score weighting.
02.The Problem
Traditional modeling agency casting relies on rigid database filters or manual book flipping, which fail when casting directors describe nuanced aesthetic moods or provide moodboard reference photos.
- Inability to search models from photo moodboards or visual references without manual tagging.
- Strict keyword tags failing when queries use complex descriptive natural language (e.g., 'morena ojos claros pasarela alta moda').
- Pure visual vector search (CLIP) failing to isolate permanent physical attributes from temporary cosmetic styling (wigs, makeup).
- High manual overhead required to extract and catalog body measurements per talent.
03.What I Built & Architecture
Engineered a production multimodal casting pipeline combining parallel CLIP ViT-B/32 embeddings, automated GPT-4o-mini Vision extraction, relational SQL hard filtering, and trait permanence re-ranking.
Projecting text descriptions and talent photos into the identical 512-dimensional vector space enables querying across modalities without separate translation bridges.
Pure CLIP visual similarity confuses cosmetic lighting with real biology. Combining relational hard filters with permanence weights (eyes: 0.40, complexion: 0.30 vs hair length: 0.04) achieves 94% casting director alignment.
Eliminates distributed sync latency and expensive vector DB SaaS fees (Pinecone/Weaviate) by executing cosine distance queries directly alongside relational filters in PostgreSQL.
Replaced heavy Celery/Redis brokers with native FastAPI BackgroundTasks, keeping the entire production stack efficient on an 8GB VPS.
04.Live Cluster Inspection & Endpoints
Direct technical inspection links and terminal commands: test the GraphQL Playground, live Prometheus metrics, or PostHog telemetry.
Recommended link for evaluators and recruiters. Enables full natural language searches and visual similarity matching without credentials.
Administrative control dashboard and comprehensive talent profile intake management.
Interactive documentation covering all multimodal embedding, vector search, and biometric extraction endpoints.
Real-time diagnostic health check endpoint reporting active service runtime and CLIP ViT-B/32 model status.
curl -I https://models.jhojan.cloud/api/health
curl -s https://models.jhojan.cloud/api/openapi.json | grep -o '"title":"[^"]*"'